
OpenShift Virtualization lets you run virtual machines (VMs) as native Kubernetes objects inside an OpenShift cluster. It is a distribution of the KubeVirt project, so the hypervisor stack is the classic KVM, QEMU, and libvirt combination that most Linux administrators already know. There is no separate hypervisor layer to install or manage. Each OpenShift worker node acts as the hypervisor, and every VM runs as a QEMU process on the node where it was scheduled, side by side with container workloads.
In this article, we explore the OpenShift Virtualization architecture from the inside. Instead of staying at the level of diagrams, we connect to a real cluster with oc and virtctl and examine every layer using the same commands you would use in production.
Summary of the key layers of OpenShift virtualization architecture
Before we go into the details, here is the architecture summarized layer by layer.
Layer | What it does |
Foundation | Deploys and configures OpenShift Virtualization as a supported set of operators, managed through the HCO and the HyperConverged CR. |
Control plane | Turns VM API objects into running VM workloads using virt-operator, virt-api, and virt-controller. |
Node and workload | Runs the VM process on the selected node through virt-handler and the virt-launcher pod. |
Storage | Provides VM disks as PVCs through Kubernetes storage APIs, with CDI and DataVolumes handling imports and clones. |
Networking | Connects VMs to the pod and external networks using Multus, NADs, and UDN/CUDN. |
Compute and migration | Schedules VMs like any other pod and moves them between nodes with live migration, using instance types for sizing. |
Data protection | Captures VM state with the native VirtualMachineSnapshot primitives, backed by CSI VolumeSnapshots. |

Automated Application-Centric Red Hat OpenShift Data Protection & Intelligent Recovery
Foundation
OpenShift Virtualization is not a single component—it is a set of operators, controllers, and node-level processes that work together to turn a VM definition into a running workload. The diagram below shows how the main pieces fit together, from the operators that install and configure the platform down to the process that runs the VM on a node.
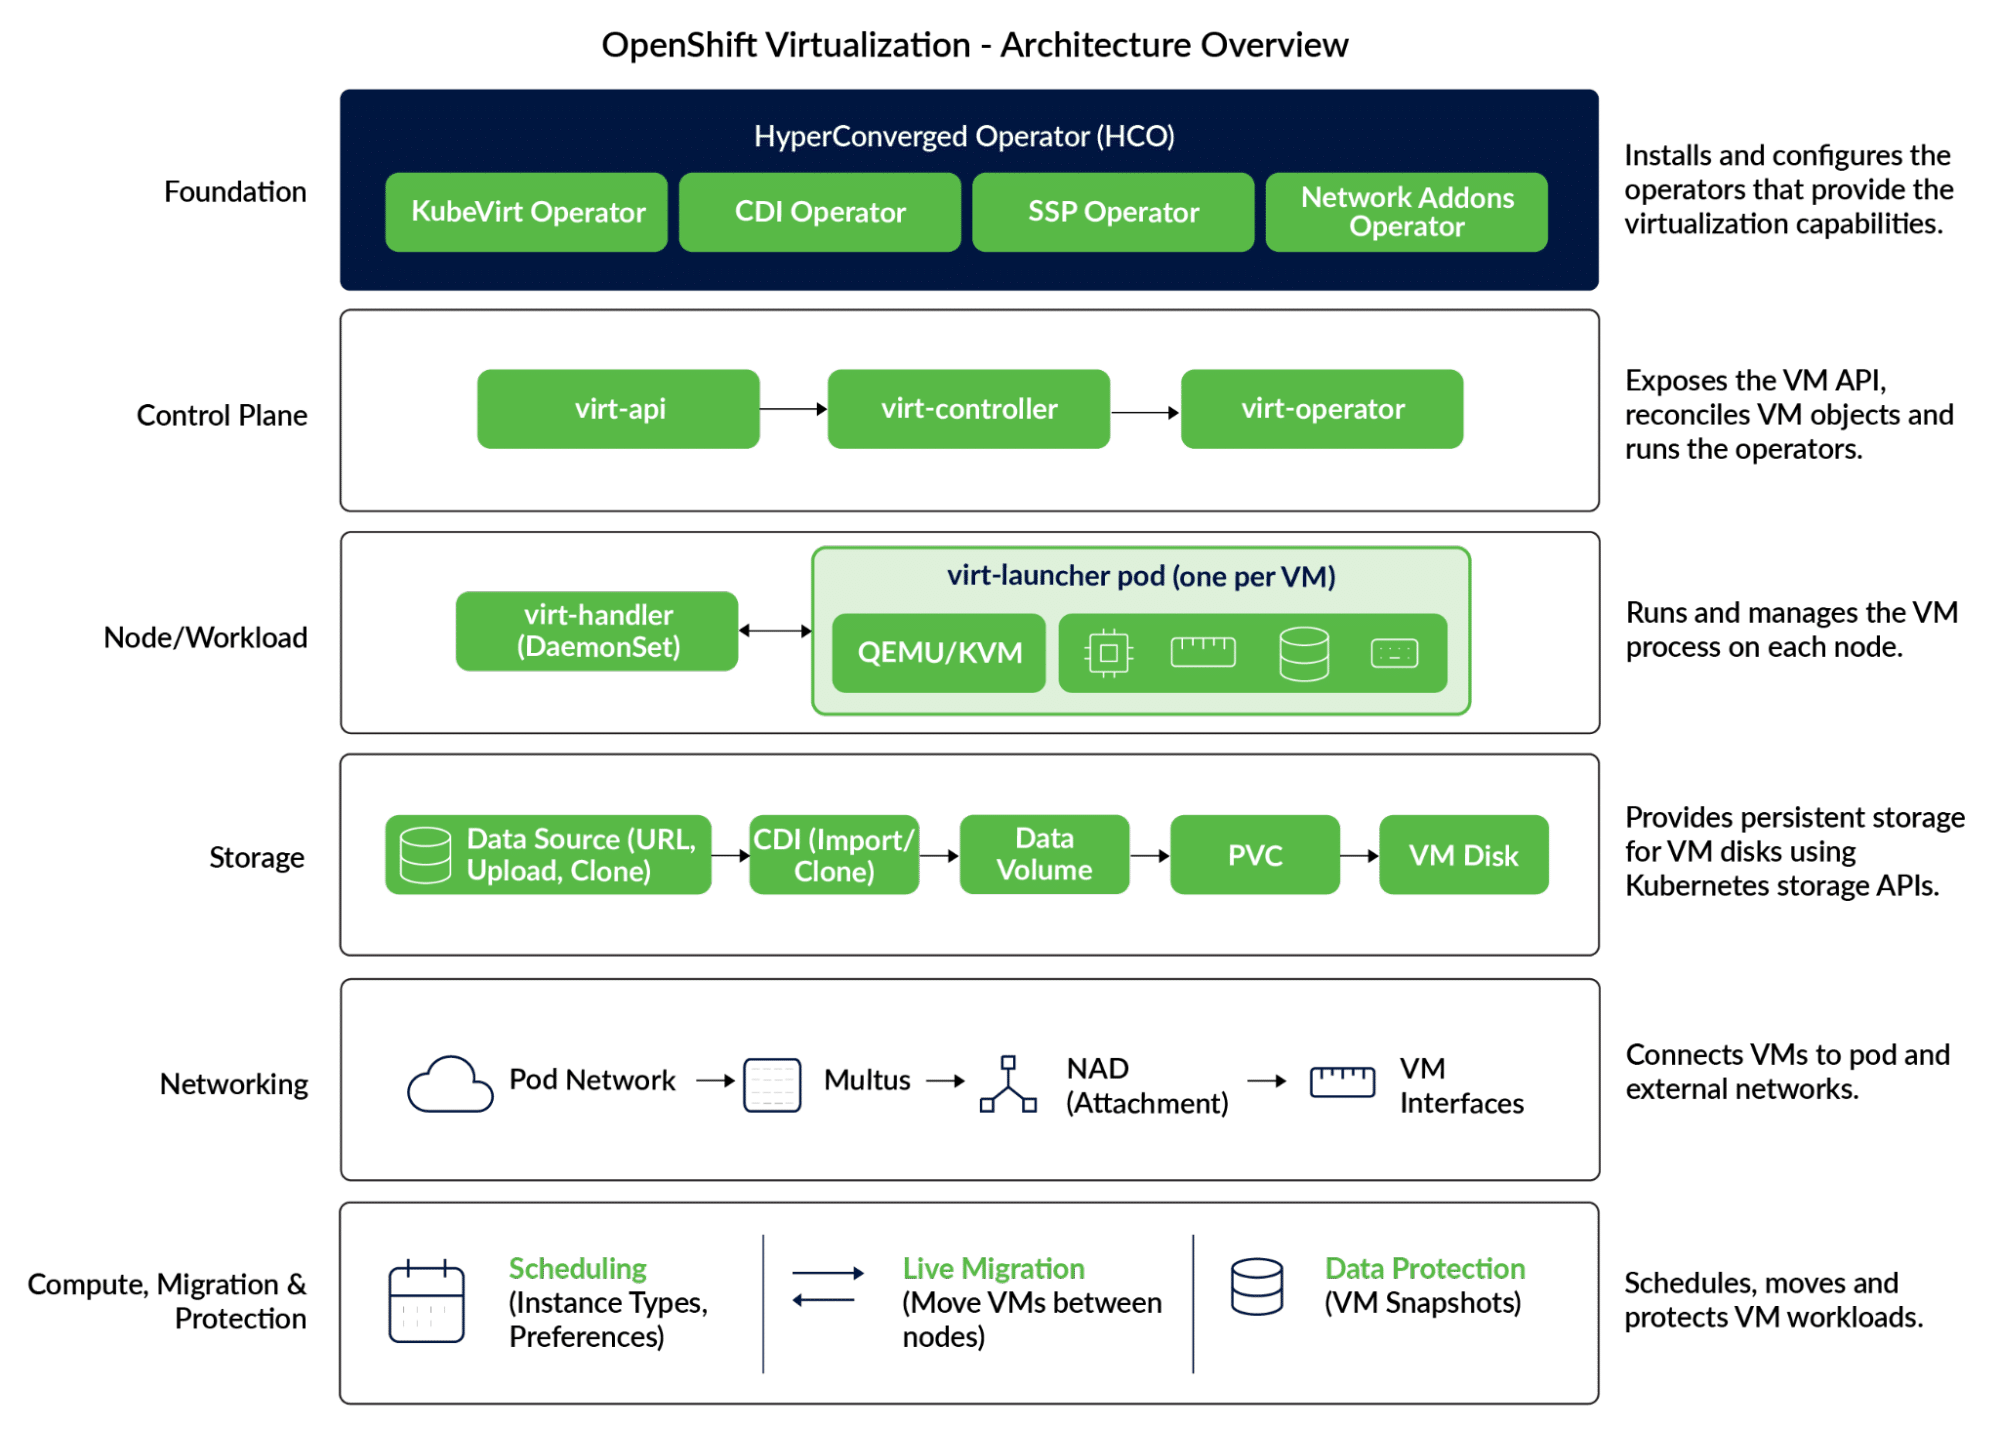
OpenShift virtualization architecture overview
Automated Red Hat OpenShift Data Protection & Intelligent Recovery
Perform secure application-centric backups of containers, VMs, helm & operators
Use pre-staged snapshots to instantly test, transform, and restore during recovery
Scale with fully automated policy-driven backup-and-restore workflows
Everything starts in the openshift-cnv namespace. This is where all the components of the product run after you install the operator from OperatorHub:
oc get pods -n openshift-cnv
The key object at this layer is the HyperConverged custom resource. This is the single entry point to configure the whole product:
oc get hyperconverged -n openshift-cnv kubevirt-hyperconverged -o yaml
The HyperConverged Cluster Operator (HCO) is often called an “operator of operators.” It does not manage VMs or storage directly; instead owning and coordinating a set of sub-operators, each taking care of a specific area:
- KubeVirt manages the virtualization control plane and the node-level components that run the VMs.
- Containerized Data Importer (CDI) handles VM disk images, including imports from a URL, uploads with virtctl, and clones between PVCs.
- Scheduling, Scale, and Performance (SSP) provides the templates, instance types, and preferences that users reference when creating a VM.
- Cluster Network Addons deploys the extra network components VMs need, such as Multus, the Linux bridge CNI, and the SR-IOV plugin.
The sub-operator objects (KubeVirt, CDI, SSP, NetworkAddonsConfig) exist, and you can list them:
oc get kubevirt,cdi,ssp,networkaddonsconfig -A
However, you should not touch them. HCO owns its configuration and will revert any changes you make outside the HyperConverged object during the next reconciliation loop. Configure everything through HyperConverged and let HCO push the changes down.
Control plane
The control plane is the group of components that takes a VM definition and turns it into something running on a node, as shown in this code:
					oc get pods -n openshift-cnv \
            -l 'kubevirt.io in (virt-api,virt-controller,virt-operator)'
There are three components worth understanding here:
- virt-operator deploys and maintains the KubeVirt control plane. It watches the KubeVirt custom resource and creates the other pods when something is missing.
- virt-api extends the Kubernetes API with virtualization objects, like VirtualMachine and VirtualMachineInstance. It also supports the actions that virtctl uses under the hood, such as opening a console or pausing a VM.
- virt-controller is the reconciliation loop for VMs. It watches VM and VMI objects and creates the launcher pod that will host the VM on the node.
The flow is easier to follow with a concrete example. Suppose you write a small VirtualMachine manifest:
					apiVersion: kubevirt.io/v1
kind: VirtualMachine
metadata:
  name: fedora-demo
spec:
  runStrategy: Always
  template:
    spec:
      domain:
        cpu:
          cores: 1
        memory:
          guest: 1Gi
        devices:
          disks:
            - name: rootdisk
              disk:
                bus: virtio
          interfaces:
            - name: default
              masquerade: {}
      networks:
        - name: default
          pod: {}
      volumes:
        - name: rootdisk
          containerDisk:
            image: quay.io/containerdisks/fedora:latest
Apply it and watch what happens:
					oc apply -f my-vm.yaml -n <namespace>
oc get vm,vmi -n <namespace>
oc get pods -n <namespace> -l kubevirt.io=virt-launcher
virt-controller picks up the VM, creates a VirtualMachineInstance (VMI), and creates the launcher pod that will host the QEMU process. The VMI represents the running instance of the VM, just as a Pod represents the running instance of a Deployment.
If a VM is not starting, oc describe vm and oc describe vmi are the first places to look. These events will tell you whether the problem is at the API level, at the controller, at the scheduler, or later, when the launcher pod tries to start QEMU.
Node and workload
So far, everything we saw runs in the control plane. Now let’s look at the node itself, starting with virt-handler. It runs as a DaemonSet, so you will find one pod on every node that can run VMs:
oc get pods -n openshift-cnv -l kubevirt.io=virt-handler -o wide
Its job is to take the VMI object from the control plane and translate it into instructions for the local libvirt daemon that starts the VM. It also reports the VM status back to the control plane.
The second component is the virt-launcher pod. For every running VM, there is one launcher pod on the node where the VM was scheduled. Inside the pod, KubeVirt runs a small set of processes that together host the VM:
oc exec -n <namespace> virt-launcher-<vm-name>-xxxxx -- ps -ef
You will see four processes that matter:
- virt-launcher-monitor (PID 1) supervises the launcher and terminates the pod cleanly if the launcher dies.
- virt-launcher is the KubeVirt agent inside the pod. It talks to virt-handler and manages the libvirt domain lifecycle.
- virtqemud is the modular libvirt daemon for QEMU, the successor to the monolithic libvirtd on modern RHEL.
- qemu-kvm is the VM itself. Everything else in this architecture exists to bring this process to life.
If you look at the qemu-kvm command line, you can see many of the design decisions that KubeVirt made for you: the emulated chipset, the SMBIOS identifying the VM as running on OpenShift Virtualization, the CPU model, and the features exposed to the guest.
One detail catches many people the first time: KubeVirt runs libvirt in session mode, not system mode, so the daemon runs as an unprivileged qemu user inside the container. To inspect the domain, use qemu:///session:
oc exec -n <namespace> virt-launcher-<vm-name>-xxxxx -- virsh -c qemu:///session list
Once you internalize that a VM is just a process inside a pod, everything else fits in place. You do not SSH into the hypervisor. You use oc, virtctl, and Kubernetes-native tools.
Storage
Every VM disk in OpenShift Virtualization is a Persistent Volume Claim (PVC). There is no datastore abstraction, no VMFS, and no VMDK files hidden on the node. The disk is a Kubernetes volume, provisioned on demand by a CSI driver, in the same way as for any other stateful workload.
The component that brings disks into the platform is the Containerized Data Importer (CDI). CDI introduces an object called DataVolume, which is a wrapper over a PVC that also takes care of populating it. A DataVolume can import a disk image from a URL, receive one from virtctl image-upload, or clone an existing PVC:
oc get dv,pvc -n <namespace>
Behind the scenes, CDI spins up a temporary importer pod that writes the data to the PVC and disappears when it is done. If your import is stuck, this is the pod to check.
There is also a StorageProfile object per storage class, with the defaults that OpenShift Virtualization recommends for that class based on the CSI driver capabilities:
oc get storageprofile
If you open one of those StorageProfiles, you will see that it is mostly about two fields: accessMode and volumeMode. These two have more impact on your VMs than any other storage setting:
- accessMode decides who can attach to the volume. Live migration requires the disk to be mounted on both the source and destination nodes simultaneously, so you need ReadWriteMany (RWX). If your storage class only supports ReadWriteOnce (RWO), live migration is not an option for those VMs.
- volumeMode decides how the volume is presented to the pod. Block gives QEMU direct access to the block device, without an extra filesystem layer in between. Filesystem creates a disk image file on top of the filesystem inside the PVC, adding overhead. For VM disks, Block is usually the better choice.
Live migration also depends on other factors, like CPU compatibility and network bandwidth, but storage is the first thing to check: Without RWX, the migration simply cannot happen.
Networking
By default, every VM in OpenShift Virtualization gets a single interface on the pod network. This is the same OVN-Kubernetes SDN used by every other pod, so the VM can reach other pods and Services right after it starts, without any extra configuration:
oc get vmi <vm-name> -n <namespace> -o jsonpath='{.status.interfaces}' | jq
The pod network is fine for VMs that only talk to other cluster workloads, but most real VMs also need to reach the outside world, so they require a second interface connected to an external network.
The modern way to declare an external network is with a ClusterUserDefinedNetwork (CUDN). A CUDN is cluster-scoped, so it requires a cluster-admin to create it, and it can be shared across many namespaces. That is exactly what you want when the same external VLAN needs to be reachable from VMs in different projects. There is also a namespaced variant, the UserDefinedNetwork (UDN), which a regular user can create inside their own namespace, but it is meant for isolated in-cluster networks, not for reaching a physical VLAN. For external connectivity, CUDN is the object you use:
oc get userdefinednetwork,clusteruserdefinednetwork -A
Whichever object you select, it is just a declaration. Somewhere, the traffic still has to leave the node and reach the physical network. There are three common ways to do this, each configured through a different object:
- Through the cluster SDN (OVN-Kubernetes localnet topology), declared with a CUDN. Traffic goes through the same SDN that all pods use, and OpenShift maps it out to a physical VLAN. This is the default and the one Red Hat recommends today.
- Through a Linux bridge on the node, declared with a NAD. Traffic bypasses the SDN and goes straight from the VM to a bridge configured on a physical interface. This is useful when you need the shortest path to the physical network.
- Through SR-IOV, also declared with a NAD. The VM gets direct hardware access to a virtual function of the physical NIC. This is useful for VMs that need very high throughput or very low latency.
For the SDN and Linux bridge options, the physical interfaces, bonds, and bridges on the nodes must exist first. That host-level configuration is applied declaratively through the NMState operator, using NodeNetworkConfigurationPolicy (NNCP) objects:
oc get nncp
The object behind all three options is the NetworkAttachmentDefinition (NAD), which is what Multus uses to attach an extra network to a pod. When you create a CUDN with the localnet topology, its NAD is generated for you. For Linux bridge and SR-IOV, you create it directly:
oc get net-attach-def -A
By default, a VM that attaches to an external localnet network has two interfaces: one on the pod network and one on the external network. Removing the pod network interface is possible, but the path depends on the mechanism:
- With a Linux bridge, you skip the default masquerade interface in the VM manifest, so the VM boots with only the bridge interface. This is the common approach in VMware migrations, where the VM has to keep its original IP on the corporate VLAN.
- With user-defined networks, you can make a Layer2 UDN or CUDN the VM’s primary network with role: Primary, which replaces the pod network. Note that this is an in-cluster overlay, not a direct attachment to a physical VLAN; localnet itself is always a secondary network and cannot be primary.
Be aware that replacing the pod network disables certain cluster-native features for that VM, such as virtctl ssh, oc port-forward, and readiness/liveness probes, because the cluster loses its default-network path to the VM.
Compute and migration
VMs in OpenShift Virtualization are scheduled with the same primitives as any other pod: node selectors, affinity, anti-affinity, and taints/tolerations. The Kubernetes scheduler decides where the VM lands based on the resource requests and constraints in the VM specification.
For sizing, two objects make things easier. VirtualMachineInstanceType defines the compute size of the VM (CPU and memory), and VirtualMachinePreference defines guest-specific behavior like the disk bus, network model, and preferred CPU topology:
					oc get virtualmachineclusterinstancetype
oc get virtualmachineclusterpreference
You reference them from a VM object with spec.instancetype and spec.preference. This lets you standardize the configuration across many VMs without repeating the same fields every time.
The most interesting operation at this layer is live migration:
					virtctl migrate <vm-name> -n <namespace>
oc get vmim -n <namespace> -w
This creates a VirtualMachineInstanceMigration (VMIM) object. Under the hood, it is a plain QEMU live migration orchestrated by KubeVirt. A new launcher pod is scheduled on the destination node, QEMU starts on that pod, the memory of the VM is copied over the network, and when the copy is complete, the VM is briefly paused on the source and resumed on the destination.
For a live migration to succeed, a few conditions must be met simultaneously: RWX storage, network reachability between the two nodes, compatible CPU models, and sufficient free memory on the destination node. If any of these are missing, the migration fails or never starts.
Data protection
The state of a VM is not just a disk; it includes the VM definition, the disks, the network configuration, cloud-init, and the secrets it references. If you only capture the disk, you are missing part of the picture.
The native primitive for capturing a VM’s state is VirtualMachineSnapshot. You create it against a running or stopped VM, and OpenShift Virtualization takes care of the rest: a VolumeSnapshot per disk through the CSI driver, and a VirtualMachineSnapshotContent for the VM definition and its associated objects. To bring the VM back, you use a VirtualMachineRestore:
oc get vmsnapshot,vmsnapshotcontent,vmrestore -n <namespace>
For online snapshots, install the QEMU guest agent inside the VM. Without it, KubeVirt cannot freeze the guest filesystem, and the snapshot is best-effort.
These primitives are good for local operations, such as taking a snapshot before an OS upgrade, but they are not a backup strategy. They live in the same cluster as the VMs they protect, with no retention policies, no cross-cluster restore, and no application-level consistency across multiple VMs.
For production, you need something on top. Kubernetes-native backup platforms use these same snapshot APIs and add the missing pieces: scheduling, retention, cross-cluster restore, and external storage targets like S3. Trilio is one of the platforms in this space, designed specifically for Kubernetes workloads and virtual machines on OpenShift Virtualization.
Conclusion
After walking through every layer, the pattern should be clear: OpenShift Virtualization is Kubernetes all the way down. The HyperConverged CR, controllers, launcher pod, and QEMU process are all normal Kubernetes objects. You can inspect and debug each one of them with oc, like any other workload.
The walkthrough also shows how much it depends on early decisions. Storage, networking, and migration are not things you adjust later because a cluster built on RWO-only storage will never live-migrate a VM, no matter how well you operate it. If you are designing a cluster right now, this is the moment to get those three right.
Data protection is one of those early decisions, too. The native snapshot primitives are part of the architecture, but they stop at the cluster boundary. For production, you need scheduling, retention, and restores that work somewhere else. Trilio does that on top of the same Kubernetes APIs we inspected here.
If you want to see how it fits your environment, you can schedule a session with a Trilio solution architect.

Like This Article?
Subscribe to our LinkedIn Newsletter to receive more educational content